
// BLOG
Research & updates
Exploring the frontiers of AI, language models, and multilingual technology
CoSHE-Eval: A Code-Switching ASR Benchmark for Hindi–English Speech
CoSHE-Eval is a 30-hour Hindi–English code-switching evaluation dataset designed to benchmark ASR systems under realistic multilingual speech conditions.
Read moreDhrith: Emotionally Intelligent ASR for India's Multilingual Voices
Dhrith is our next-generation ASR model that listens beyond words. It understands emotion, rhythm, and code-switched language.
Read more
Introducing Pragna-1B: Soket AI Labs' Multilingual Language Model for Indian Languages
We at Soket AI Labs are thrilled to unveil India's first open source multilingual model, Pragna-1B available in four Indian languages.
Read more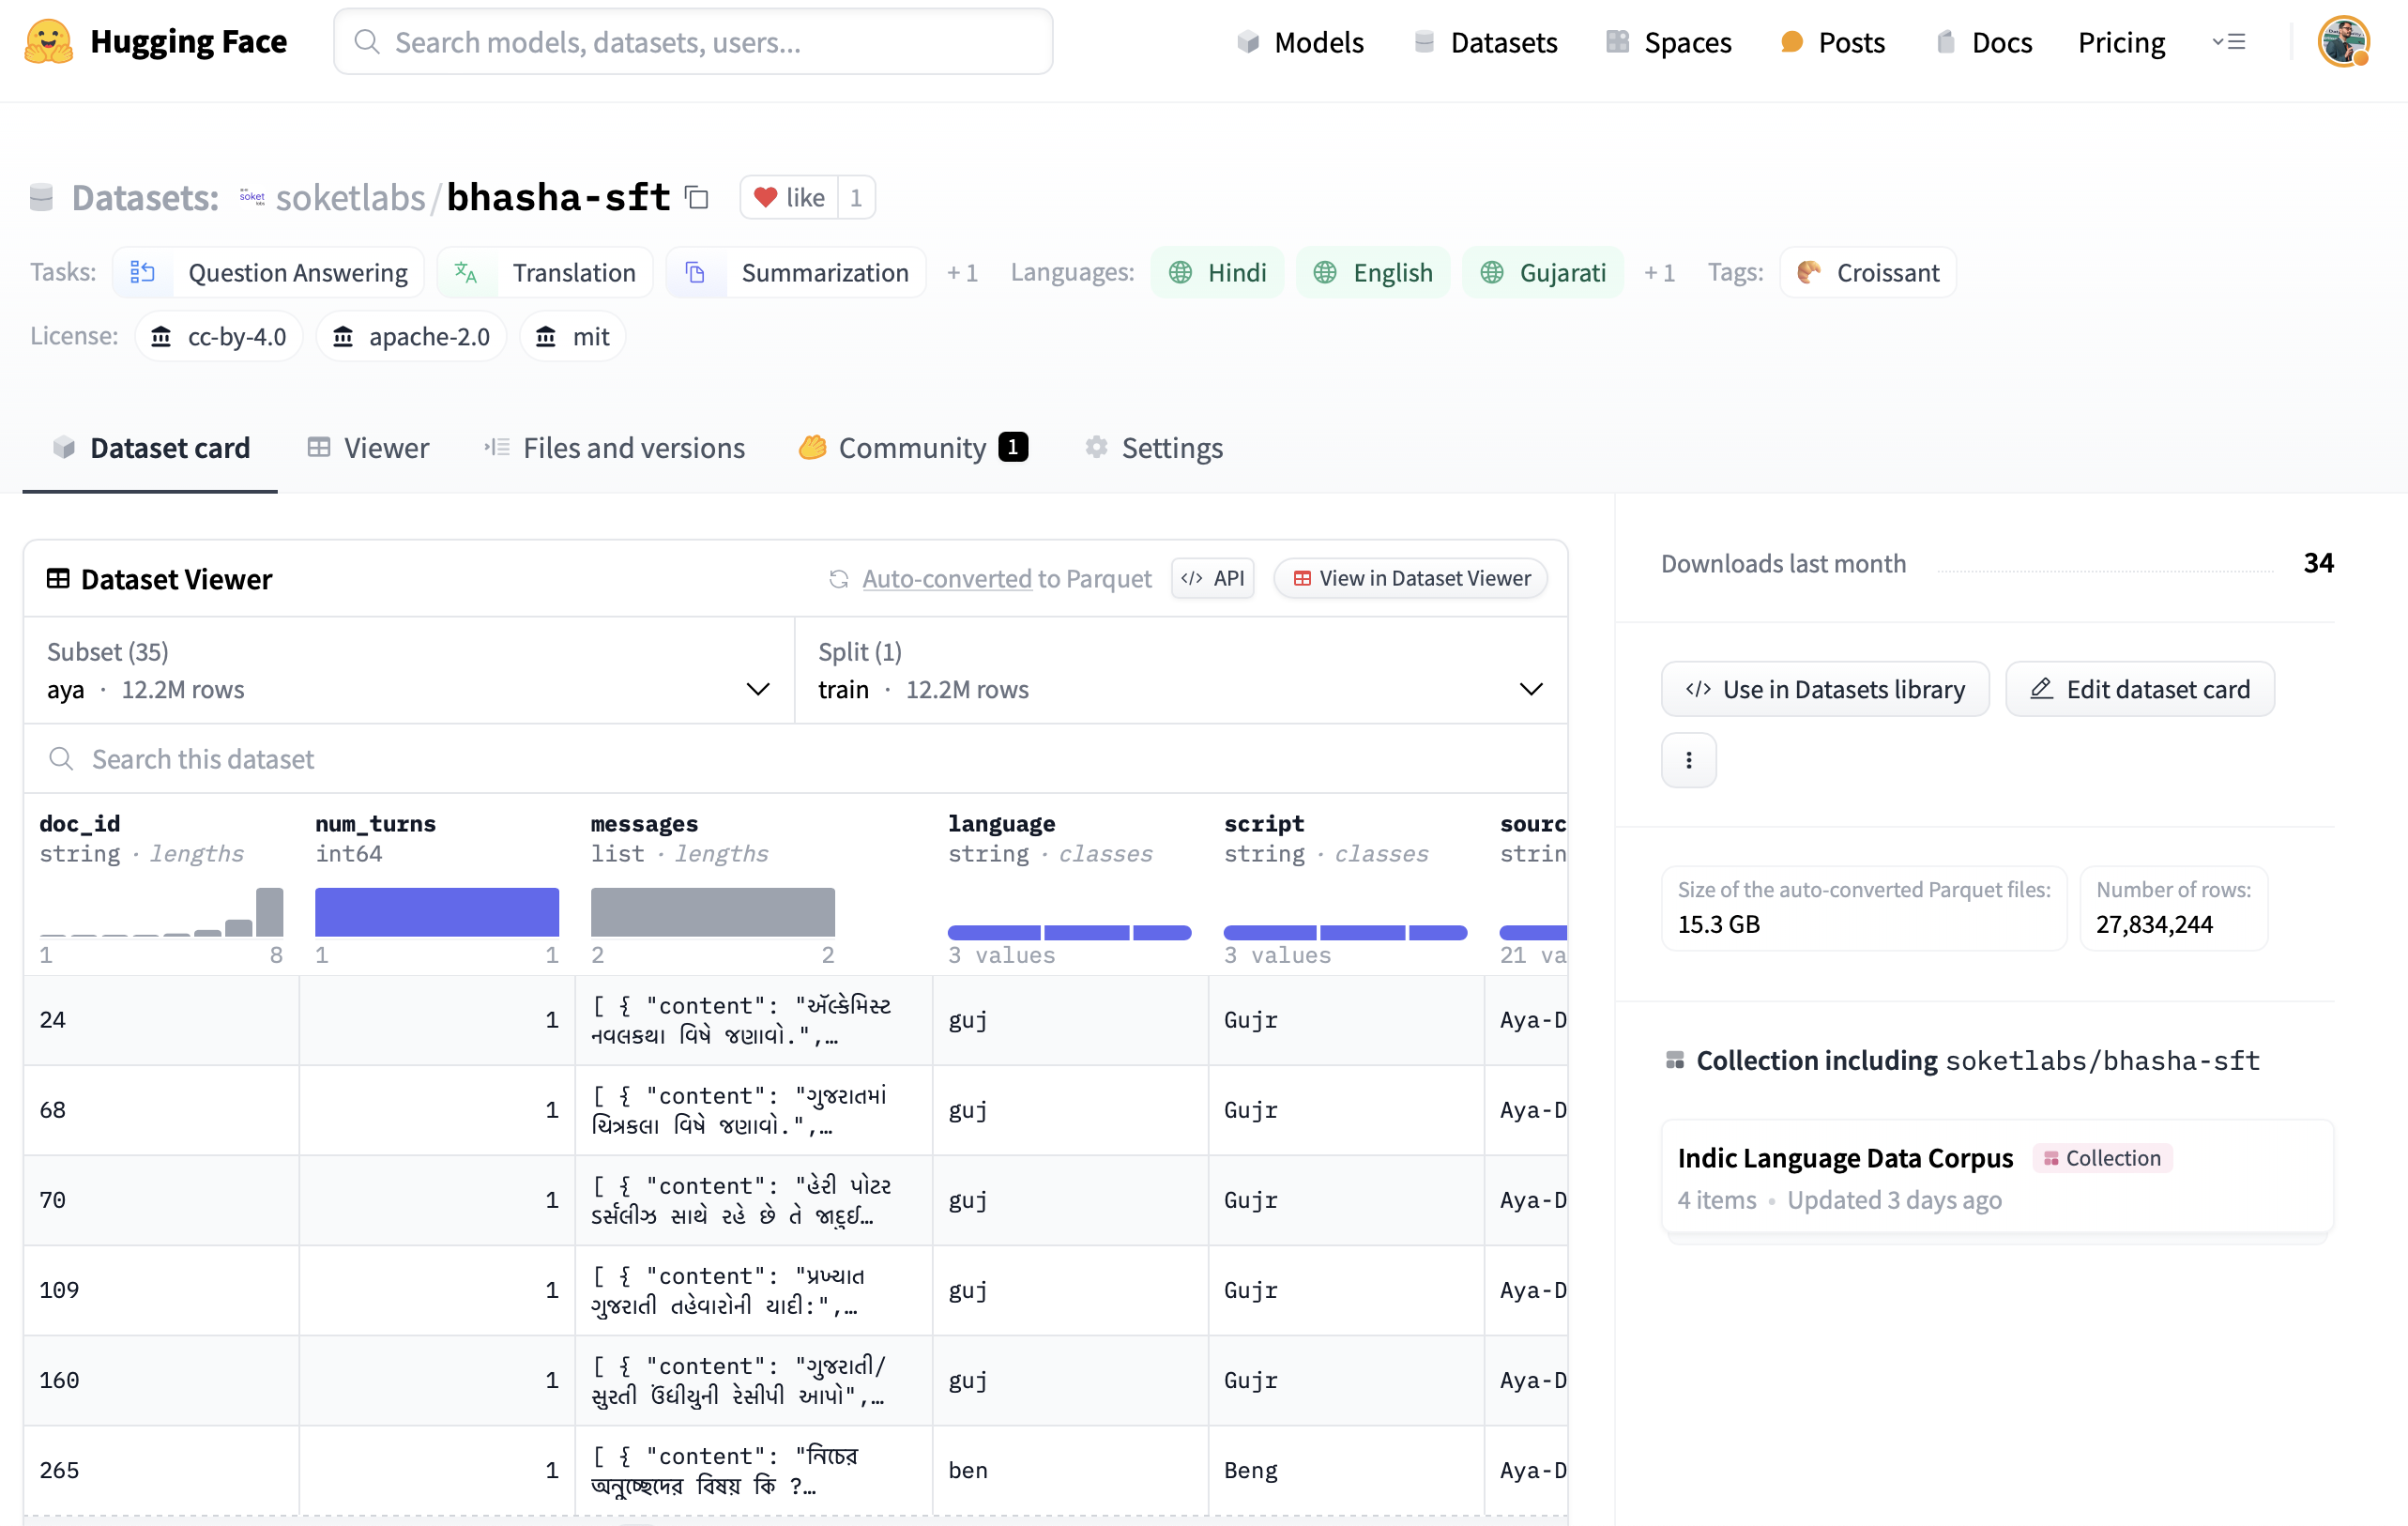
Availability of the Bhasha SFT Dataset for Supervised Fine-Tuning of Indic Language Models
An extensive collection curated by Soket AI Labs for the supervised fine-tuning of Multilingual Large Language Models, focusing on Indic languages.
Read more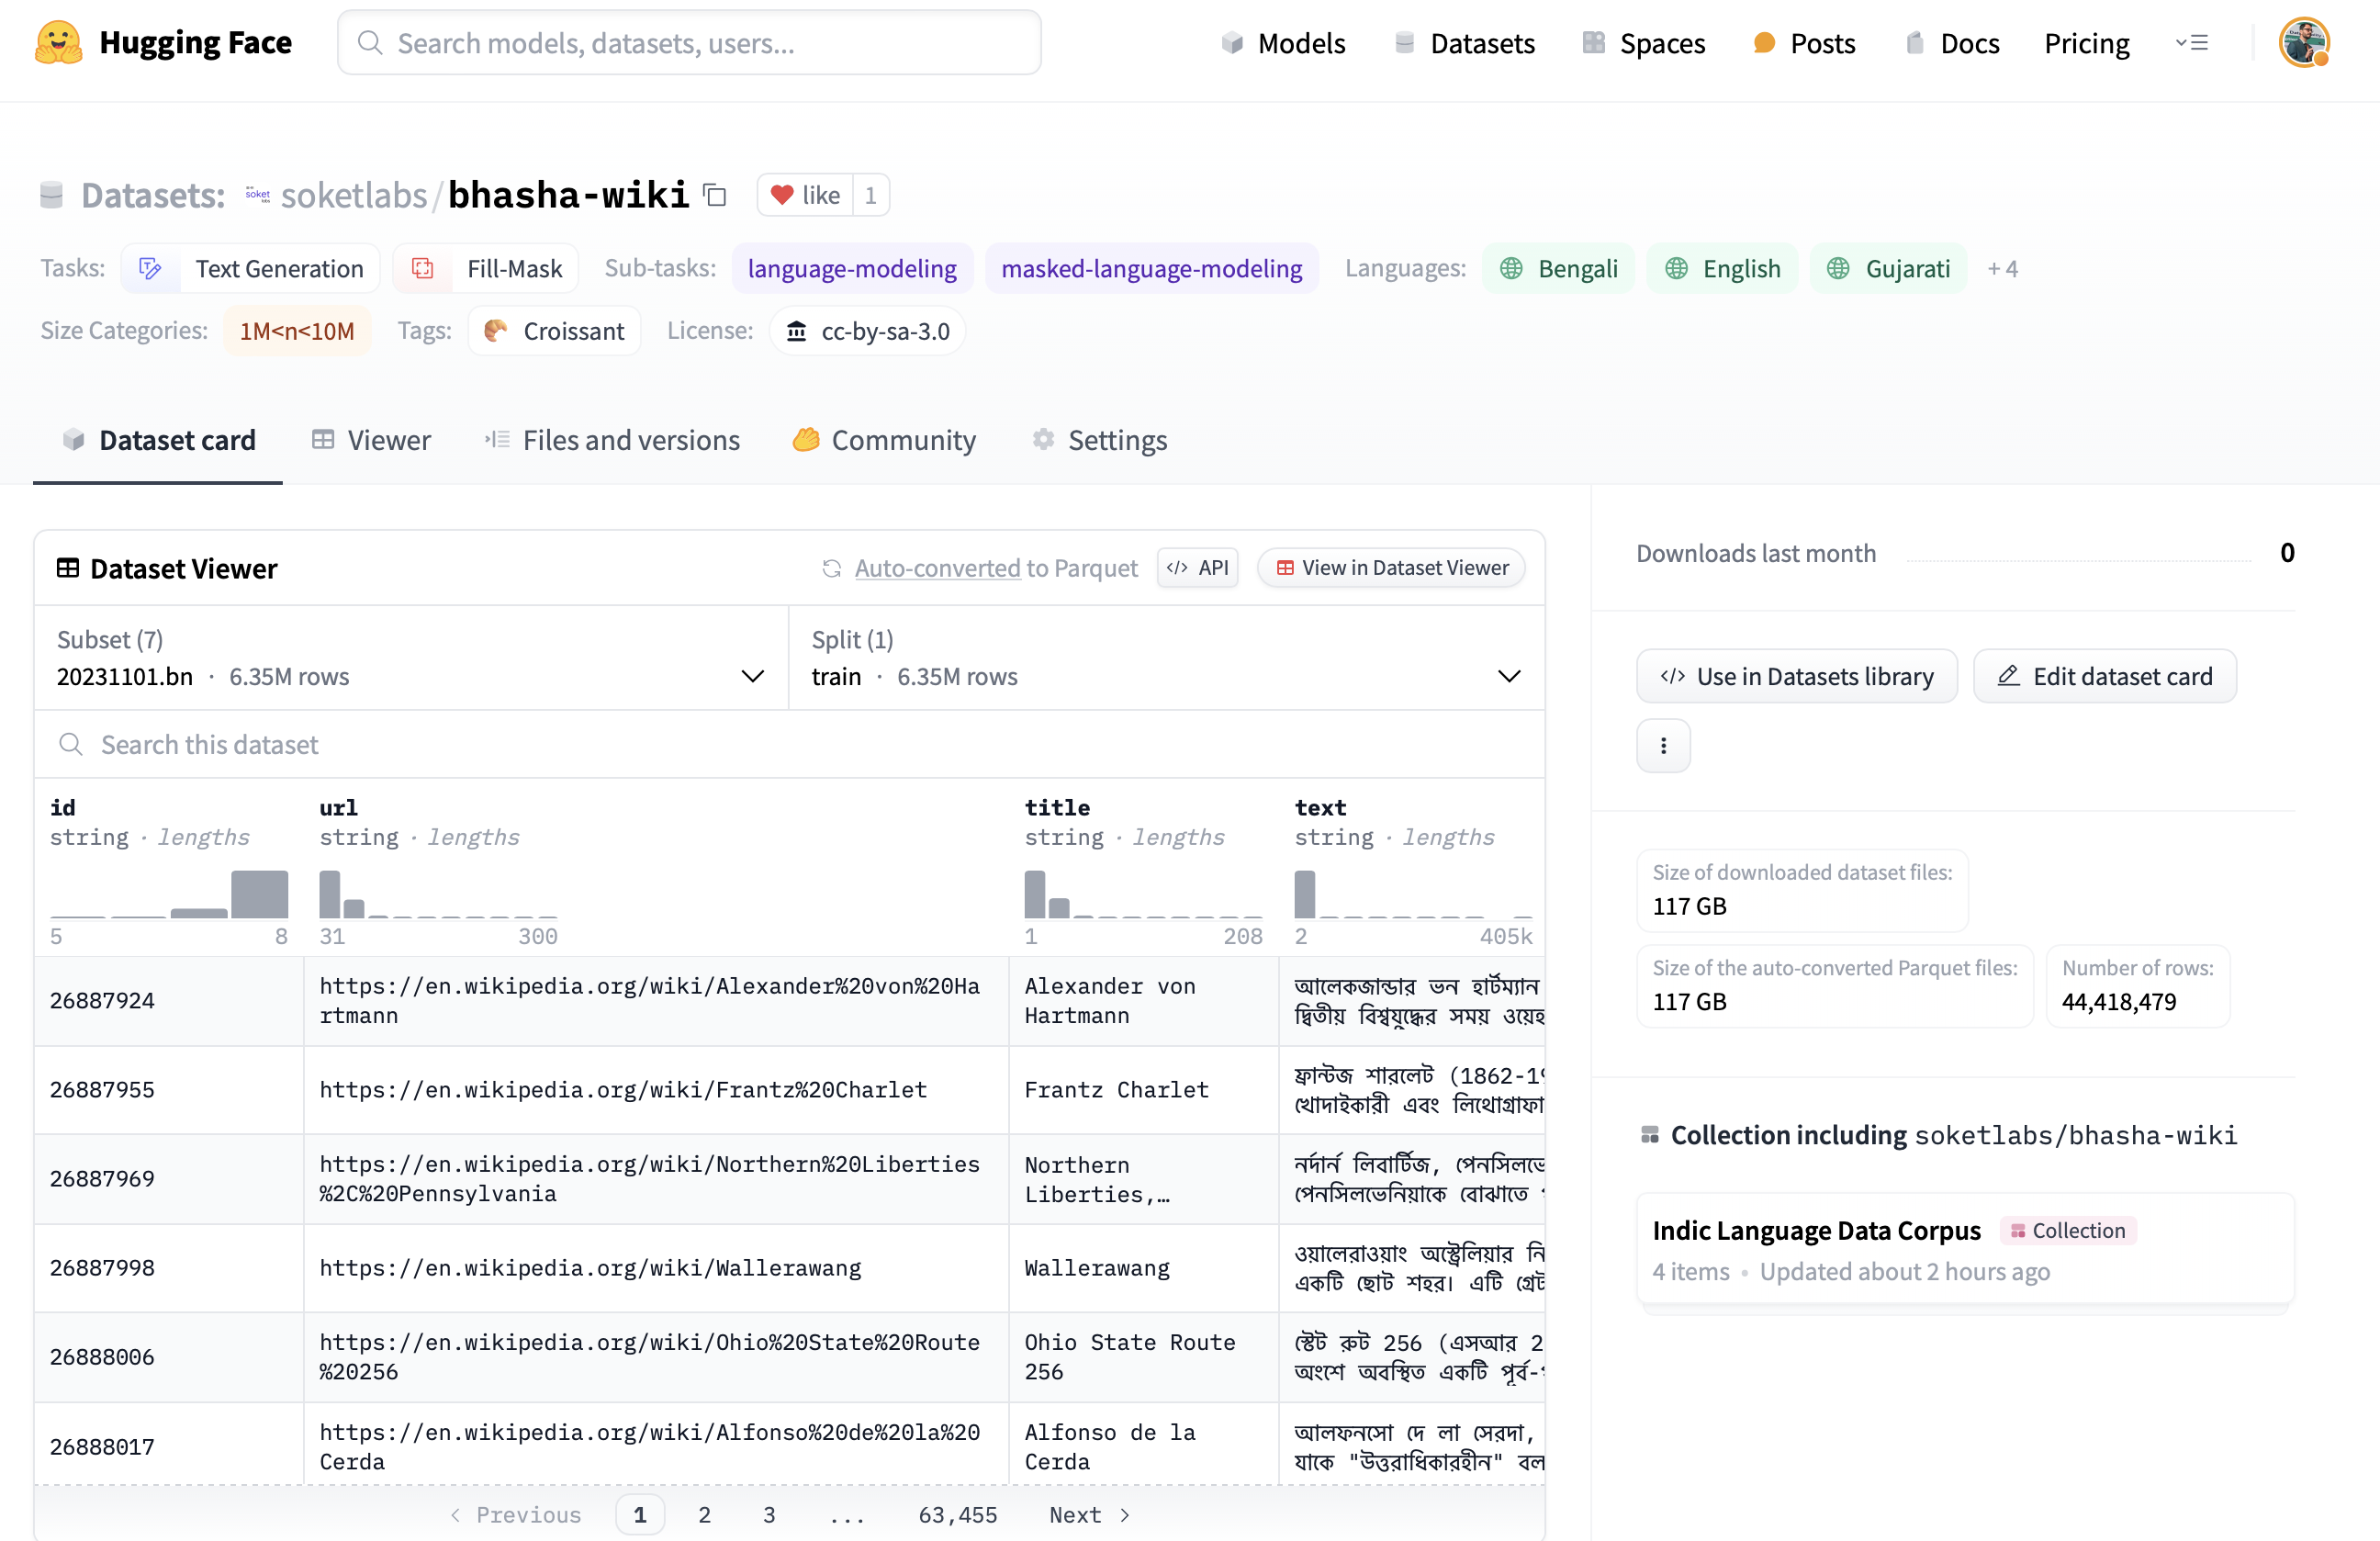
Introducing the "Bhasha" Series: Advancements in Indic Language AI Datasets
The "Bhasha" series datasets are engineered to support the development of AI models attuned to the linguistic and cultural nuances of India.
Read more